Neither True nor FalseDo LLMs Represent Truth-Value Gaps in Plural Predication?
Abstract
Large Language Models (LLMs) are increasingly being used to summarize and verify claims in critical sources that inform consequential decisions. Such claims are full of plural definites. If three of five patients improved after taking drug A, the claim the patients improved after drug A is not true, since two did not, yet its negation, the patients didn't improve after drug A, is not true either, since three did. In formal semantics, this truth-value gap is known as the Homogeneity Gap: both the plural definite and its negation are neither true nor false when the property holds for only a fraction of the plural referent. A model that cannot represent this gap turns mixed evidence into a clean verdict, an error that can be costly in high-stakes use. We introduce HomogeneityNLI, a diagnostic dataset of 1,000 minimal-pair items crossing determiner, polarity, and group composition across ten logical conditions. Evaluating seven open-weight models, we uncover a pervasive Bivalence Bias: models assign plural definites their homogeneous truth conditions. In the zero-shot setting, no model recognizes the gap for both polarities in more than 15% of scenarios, and negated definites are judged False in 84% of cases. Explicit linguistic rules, chain-of-thought, and enumeration prompts produce unstable, model-specific effects that often entrench the bias. Our findings indicate that current open-weight LLMs acquire the truth conditions of plural predication but not its trivalent logic, and cannot yet be trusted to summarize or verify claims whose evidence is mixed.
Why This Matters
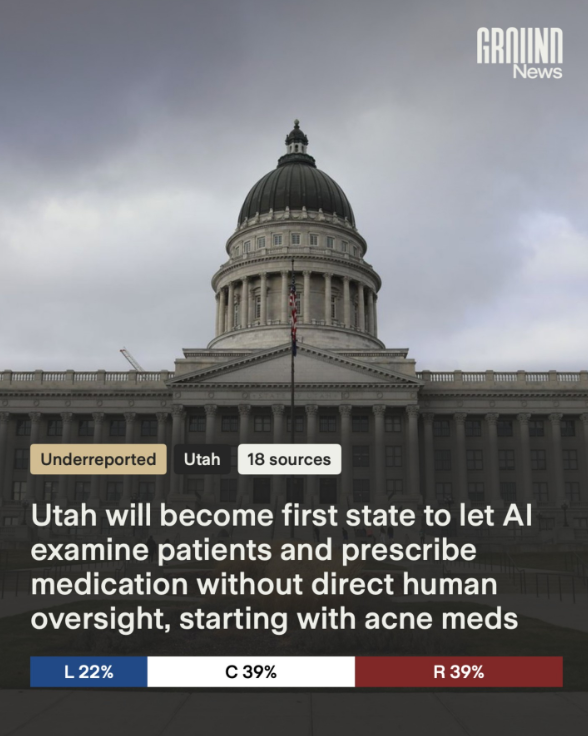
AI systems are increasingly being given real decision-making roles. Utah, for example, has become the first state to let an AI examine patients and prescribe medication without a doctor signing off on each prescription [1].
Many of today's AI systems are built on large language models, which learn from text, and language is complex. For example, a claim can be neither true nor false when the evidence is mixed, a phenomenon known in linguistics as homogeneity. Adults draw this distinction readily [2].
Our study shows that LLMs have not acquired this understanding. None of the models we tested shows the adult pattern as its dominant one, and some interpret these statements the way a subgroup of 4–5-year-olds does [3].
So as we hand AI more decisions and less human oversight, we should ask whether it fully understands the language it acts on (Nakshbandi et al., 2026). If this topic interests you, explore the project below and read our paper on arXiv.
- Ground News (2026). Utah clears world's first autonomous prescriptions without doctors.
- Križ & Chemla (2015). Two methods to find truth-value gaps and their application to the projection problem of homogeneity. Natural Language Semantics.
- Tieu, Križ & Chemla (2019). Children's acquisition of homogeneity in plural definite descriptions. Frontiers in Psychology.
The Homogeneity Gap
With a distributive predicate, a plural definite is true when every member has the property, false when none has it, and neither when the group is mixed (Löbner 1987; Schwarzschild 1994; Križ 2015).
Symmetrically for the X not-P. In a mixed group, complementarity fails: ⟦the X not-P⟧ ≠ 1 − ⟦the X P⟧. Quantifiers keep it: ⟦not all the X P⟧ = 1 − ⟦all the X P⟧.
The gap has been derived as a presupposition, as supervaluation over an existential and a universal reading, and as recursive strengthening by implicature. Tieu, Križ & Chemla (2015) classify answers to the positive and negated definite in a mixed situation into three profiles:
A binary judgment task cannot tell not true from false. With three response options, “reject both” splits into a genuine gap (Neither, Neither), a mixed pattern and a bivalent collapse (False, False).
HomogeneityNLI
Each scenario pairs a plural noun phrase with a distributive predicate and is expanded into ten items that differ only in the context sentence and the hypothesis, so every group is an exact minimal pair of every other.
| Group | Context | Hypothesis | Gold | Role |
|---|
All premises begin “Five hearts were drawn on the card.” followed by “Three of them were red and two were not.” (GAP), “Every one of them was red.” (ALL) or “None of them were red.” (NONE). Uniform contexts say every one of them rather than all to avoid lexical overlap with the quantified hypotheses. Labels are True / False / Neither: in a gap context the premise fully specifies the facts, so what is missing is a classical truth value, not information. *True under the literal meaning of some; False under the scalar implicature some but not all.
Browse the Scenarios
| ID | Context | Hypothesis | Gold |
|---|
Models and Prompts
Seven instruction-tuned open-weight models (7–9B), each with its chat template, greedy decoding and at most 512 new tokens.
Results
For each of the 100 scenarios, a model's answers to the positive definite (A) and the negated definite (B) in the mixed group form one response pattern. Only the Gap pattern reflects the truth-value gap.
Metrics
A, B, C, D: accuracy per group. Ctrl: mean accuracy on the uniform-context controls E–H. EBR / UBR: share of True on A / B (existential and universal readings). HGR: both answers Neither. BCR: both False. ΔNA = AccD − UBR: whether the model separates not all the patients improved after taking drug A from the patients didn't improve after taking drug A. Ctrl OK: scenarios (of 100) whose four definite controls are all correct. † Degenerate run in which the controls fail; excluded from pooled analyses.
Analysis
Truth conditions are right; the truth value is wrong
In chain-of-thought rationales that end in False, models restate the positive definite as a universal claim 92% of the time (“The hypothesis claims that all cows are in the barn. Since one cow is not in the barn, the hypothesis is false.”). For the negated definite, 48% restate it as none.
The rationales name exactly the conditions under which the theories predict truth, and then treat their failure as falsity: models map not true onto false.
Tolerance near the top, and only on one side
When all but one member has the property, models accept the positive definite in 25% of cases, compared with 9% for balanced groups and 6% when only one member has it, mirroring non-maximality in human language.
The tolerance is one-sided: when only one member has the property, the negated definite is accepted in just 10% of cases, barely more than for balanced groups (9%). The gap is recognized most often for maximally mixed groups (56% Neither on A, vs. 30–34% otherwise).
Predicates shift which classical value models pick
Action predicates are accepted in 23% of mixed scenarios (The patients improved after taking drug A), properties in only 2% (The hearts were red), and locations and states in 14% each.
Predicate class does not affect the use of Neither: semantics changes which classical value models choose, not whether they recognize the gap.
Both charts: zero-shot answers in GAP contexts. The model selector applies to both.
BibTeX
@misc{nakshbandi2026truefalsellmsrepresent,
      title={Neither True nor False: Do LLMs Represent Truth-Value Gaps in Plural Predication?},
      author={Duaa Nakshbandi and Zhiyu An and Yiping Li and Sachin Giri and Wan Du},
      year={2026},
      eprint={2610.14438},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2610.14438},
}
HomogeneityNLI is available on Hugging Face under CC BY 4.0; the evaluation code will be released under the same license.